This is my first entry in my Statsmodels Project Summer 2011 blog. I will update this blog weekly as the summer goes by with information regarding progress on my work for the scikits.statsmodels Python library.
In order to complete the preparation process for the statsmodels Google Summer of Code sponsorship, I wrote a quick patch that included a cointegration test. As of now, the test can only be run on a bivariate system with a simple Dickey-Fuller test on the residuals, using the Mackinnon [1] critical values. I would like to expand the functionality of this test to allow for Augmented Dickey-Fuller tests of the residuals and also tests of multivariate cointegrated systems. This patch served as a nice way to dive into what time series methods scikits.statsmodels currently includes in its toolbox and where to go from here.
Saturday, April 23, 2011


Tuesday, June 22, 2010
Statsmodels: GSoC Week 4 Update
I spent the last week finishing up the paper that I submitted to accompany my talk at the SciPy conference. I am really looking forward to going to Austin and hearing all the great talks (plus I hear the beer is cheap and the food and music are good, which doesn't hurt). In addition to finishing up the paper, I have started to clean up our time series code.
So far this has included finishing the augmented Dickey-Fuller (ADF) test for unit roots. The big time sink here is that the ADF test-statistic has a non-standard distribution in most cases. The ADF test statistic is obtained by running the following regression
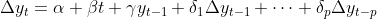
One approach to testing for a unit root means testing the t-stat on the coefficient on the lagged level of y. The actual distribution for this statistic, however, is not Student's t. Many software packages use the tables in Fuller (1976, updated to 1996 version or not) in order to get the critical values for the test statistic depending on the sample size. They use linear interpolation for sample sizes not included in the table. The p-values for the obtained test statistic are usually obtained using MacKinnon's (1994) study that estimated regression surfaces of these distributions via Monte Carlo simulation.
While we do use MacKinnon's approximate p-values from the 1994 paper, MacKinnon wrote a note updating this paper in early 2010, which gives new regression surface results for obtaining the critical values. We use these new results for the critical values. Therefore, when using our ADF test, it is advised that if the p-value is close to the reject/accept region then the critical values should be used in place of the p-value to make the ultimate decision.
We can illlustrate the use of ADF. Note that this version is only in my branch and that it is still in the sandbox, even though it has now been tested, because the API and returned results may change. We will demonstrate on a series that we can easily guess is non-stationary, real GDP.
The return values are the test statistic, its p-value (the null-hypothesis here is that the series does contain a unit root), the number of lags of the differences used, the number of observations for the regression, and a dictionary containing the critical values at the respective confidence levels. The regression option controls the type of regression (ie., whether to include a constant or a linear or quadratic time trend), and the autolag option has three options for choosing the lag length to help correct for serial correlation in the regression. There are 'AIC', 'BIC', and 't-stat'. The former two choose the lag length that maximizes the infofrmation criterion, the latter chooses the lag length based on the significance of the lag. This starts with maxlag and works its way down. The docstring has more detailed information.
Beyond this, I have been working on an autocorrelation function (acf), a partial autocorrelation function (pacf), and Q-Statistics (Box-Ljung test). Next up for this week is finishing my VAR class with identification schemes. After this, I will work to integrate post-estimation tests into our results classes, most likely using some sort of mix-in classes and attach test containers to the results objects for test results. Then it's off to the SciPy conference. There I will hopefully be participating in the stats sprint, helping out with the docs marathon and discussing what we need for the future of statistics and Python.
So far this has included finishing the augmented Dickey-Fuller (ADF) test for unit roots. The big time sink here is that the ADF test-statistic has a non-standard distribution in most cases. The ADF test statistic is obtained by running the following regression
One approach to testing for a unit root means testing the t-stat on the coefficient on the lagged level of y. The actual distribution for this statistic, however, is not Student's t. Many software packages use the tables in Fuller (1976, updated to 1996 version or not) in order to get the critical values for the test statistic depending on the sample size. They use linear interpolation for sample sizes not included in the table. The p-values for the obtained test statistic are usually obtained using MacKinnon's (1994) study that estimated regression surfaces of these distributions via Monte Carlo simulation.
While we do use MacKinnon's approximate p-values from the 1994 paper, MacKinnon wrote a note updating this paper in early 2010, which gives new regression surface results for obtaining the critical values. We use these new results for the critical values. Therefore, when using our ADF test, it is advised that if the p-value is close to the reject/accept region then the critical values should be used in place of the p-value to make the ultimate decision.
We can illlustrate the use of ADF. Note that this version is only in my branch and that it is still in the sandbox, even though it has now been tested, because the API and returned results may change. We will demonstrate on a series that we can easily guess is non-stationary, real GDP.
In [1]: import scikits.statsmodels as sm

In [2]: from scikits.statsmodels.sandbox.tsa.stattools import adfuller

In [3]: data = sm.datasets.macrodata.load()

In [4]: realgdp = data.data['realgdp']

In [5]: adf = adfuller(realgdp, maxlag=4, autolag=None, regression="ct")

In [6]: adf
Out[6]:
(-1.8566384063254346,
 0.67682917510440099,
 4,
 198,
 {'1%': -4.0052351400496136,
  '10%': -3.1402115863254525,
  '5%': -3.4329000694218998})
The return values are the test statistic, its p-value (the null-hypothesis here is that the series does contain a unit root), the number of lags of the differences used, the number of observations for the regression, and a dictionary containing the critical values at the respective confidence levels. The regression option controls the type of regression (ie., whether to include a constant or a linear or quadratic time trend), and the autolag option has three options for choosing the lag length to help correct for serial correlation in the regression. There are 'AIC', 'BIC', and 't-stat'. The former two choose the lag length that maximizes the infofrmation criterion, the latter chooses the lag length based on the significance of the lag. This starts with maxlag and works its way down. The docstring has more detailed information.
Beyond this, I have been working on an autocorrelation function (acf), a partial autocorrelation function (pacf), and Q-Statistics (Box-Ljung test). Next up for this week is finishing my VAR class with identification schemes. After this, I will work to integrate post-estimation tests into our results classes, most likely using some sort of mix-in classes and attach test containers to the results objects for test results. Then it's off to the SciPy conference. There I will hopefully be participating in the stats sprint, helping out with the docs marathon and discussing what we need for the future of statistics and Python.
Fuller, W.A.  1996.  Introduction to Statistical Time Series. 2nd ed.  Wiley.


MacKinnon, J.G. 1994.  "Approximate asymptotic distribution functions for
    unit-root and cointegration tests.  Journal of Business and Economic
    Statistics 12, 167-76.

MacKinnon, J.G. 2010. "Critical Values for Cointegration Tests."
    Queen's University, Dept of Economics, Working Papers.  Available at
    http://ideas.repec.org/p/qed/wpaper/1227.html
Friday, June 11, 2010
Statsmodels: GSoC Week 3 Update
[Edit: Formatting should be fixed now. I will not be reformatting old posts though, so that they don't get reposted at Planet SciPy]
Last week was spent mainly ensuring that I pass my comps and remain a PhD student. This week was much more productive for coding. For now, all changes are in my branch and have not been merged to trunk, but I will describe the two big changes.
The first concerns the datasets package. This one is not all that exciting, but suffice it to say that the datasets are now streamlined and use the Bunch pattern to load the data. Thanks, Gaël, for pointing this out. I also rewrote a bit of David's datasets proposal from scikits-learn to reflect the current design of our datasets and thoughts. You can see it here (soon to be on the docs page). We are making an effort to ensure that our datasets are going to be similar to those of scikits-learn.
The second change was an improvement of the fitting of maximum likelihood models and the start of a GenericLikelihoodModel class. Maximum likelihood based models (mainly discrete choice models in the main code base right now) can now be fit using any of the unconstrained solvers from scipy.optimize (Nelder-Mead, BFGS, CG, Newton-CG, Powell) plus Newton-Raphson. To take a simple example to see how it works, we can fit a Probit model.
All of the options for the solvers are available and are documented in the fit method. As you can see, some of the default values need to be changed to ensure (accurate) convergence. The Results objects that are returned have two new attributes.
In [10]: res_powell.mle_retvals
Out[10]:
{'converged': True,
'direc': array([[ 7.06629660e-02, -3.07499922e-03, 5.38418734e-01,
-4.19910465e-01],
[ 0.00000000e+00, 1.00000000e+00, 0.00000000e+00,
0.00000000e+00],
[ 1.49194876e+00, -6.64992809e-02, -6.96792443e-03,
-3.22306873e+00],
[ -5.36227277e-02, 1.18544093e-01, -8.75205765e-02,
-2.42149981e+00]]),
'fcalls': 568,
'fopt': 12.818804069990534,
'iterations': 12,
'warnflag': 0}
In [11]: res_powell.mle_settings
Out[11]:
{'callback': None,
'disp': 1,
'fargs': (),
'ftol': 1e-08,
'full_output': 1,
'maxfun': None,
'maxiter': 35,
'optimizer': 'powell',
'retall': 0,
'start_direc': None,
'start_params': [0, 0, 0, 0],
'xtol': 0.0001}
The dict mle_retvals contains all of the values that are returned from the solver if the full_output keyword is True. The dict mle_settings contains all of the arguments passed to the solver, including the defaults so that these can be checked after the fit. Again, all settings and returned values are documented in the fit method and in the results class, respectively.
Lastly, I started a GenericLikelihoodModel class. This is currently unfinished, though the basic idea is laid out. Take again the Probit example above using Lee Spector's educational program data. And assume we didn't have the Probit model from statsmodels. We could use the new GenericLikelihoodModel class. There are two ways (probably more) to proceed. For those comfortable with object oriented programming and inheritance in Python, we could subclass the GenericLikelihoodModel, defining our log-likelihood method.
Now this model could be fit, using any of the methods that only require an objective function, i.e., Nelder-Mead or Powell.
The main drawback right now is that all statistics that rely on the covariance of the parameters, etc. will use numeric gradients and Hessians, which can lessen that accuracy of those statistics. This can be overcome by providing score and hessian methods as loglike was provided above. Of course, for more complicated likelihood functions this can soon become cumbersome. We are working towards more accurate numerical differentiation and discussing options for automatic or symbolic differentiation.
The main advantage as opposed to just writing your likelihood and passing it to a solver is that you have all of the (growing number of) statistics and tests available to statsmodels right in the generic model.
I would also like to accommodate those who are less familiar with OOP and inheritance in Python. I haven't quite worked out the final design for how this would go yet. Right now, you could do the following, though I don't think it quite meets the less complicated goal.
There are still a few design issues and bugs that need to be worked out with the last example, but the basic idea is there. That's all for now.
Last week was spent mainly ensuring that I pass my comps and remain a PhD student. This week was much more productive for coding. For now, all changes are in my branch and have not been merged to trunk, but I will describe the two big changes.
The first concerns the datasets package. This one is not all that exciting, but suffice it to say that the datasets are now streamlined and use the Bunch pattern to load the data. Thanks, Gaël, for pointing this out. I also rewrote a bit of David's datasets proposal from scikits-learn to reflect the current design of our datasets and thoughts. You can see it here (soon to be on the docs page). We are making an effort to ensure that our datasets are going to be similar to those of scikits-learn.
The second change was an improvement of the fitting of maximum likelihood models and the start of a GenericLikelihoodModel class. Maximum likelihood based models (mainly discrete choice models in the main code base right now) can now be fit using any of the unconstrained solvers from scipy.optimize (Nelder-Mead, BFGS, CG, Newton-CG, Powell) plus Newton-Raphson. To take a simple example to see how it works, we can fit a Probit model.
In [1]: import scikits.statsmodels as sm
In [2]: data = sm.datasets.spector.load()
In [3]: data.exog = sm.add_constant(data.exog)
In [4]: res_newton = sm.Probit(data.endog, data.exog).fit(method="newton")
Optimization terminated successfully.
Current function value: 12.818804
Iterations 6
In [5]: res_nm = sm.Probit(data.endog, data.exog).fit(method="nm", maxiter=500)
Optimization terminated successfully.
Current function value: 12.818804
Iterations: 439
Function evaluations: 735
In [6]: res_bfgs = sm.Probit(data.endog, data.exog).fit(method="bfgs")
Optimization terminated successfully.
Current function value: 12.818804
Iterations: 15
Function evaluations: 21
Gradient evaluations: 21
In [7]: res_cg = sm.Probit(data.endog, data.exog).fit(method="cg", maxiter=250)
Optimization terminated successfully.
Current function value: 12.818804
Iterations: 188
Function evaluations: 428
Gradient evaluations: 428
In [8]: res_ncg = sm.Probit(data.endog, data.exog).fit(method="ncg", avextol=1e-8)
Optimization terminated successfully.
Current function value: 12.818804
Iterations: 12
Function evaluations: 14
Gradient evaluations: 12
Hessian evaluations: 12
In [9]: res_powell = sm.Probit(data.endog, data.exog).fit(method="powell", ftol=1e-8)
Optimization terminated successfully.
Current function value: 12.818804
Iterations: 12
Function evaluations: 568
In [2]: data = sm.datasets.spector.load()
In [3]: data.exog = sm.add_constant(data.exog)
In [4]: res_newton = sm.Probit(data.endog, data.exog).fit(method="newton")
Optimization terminated successfully.
Current function value: 12.818804
Iterations 6
In [5]: res_nm = sm.Probit(data.endog, data.exog).fit(method="nm", maxiter=500)
Optimization terminated successfully.
Current function value: 12.818804
Iterations: 439
Function evaluations: 735
In [6]: res_bfgs = sm.Probit(data.endog, data.exog).fit(method="bfgs")
Optimization terminated successfully.
Current function value: 12.818804
Iterations: 15
Function evaluations: 21
Gradient evaluations: 21
In [7]: res_cg = sm.Probit(data.endog, data.exog).fit(method="cg", maxiter=250)
Optimization terminated successfully.
Current function value: 12.818804
Iterations: 188
Function evaluations: 428
Gradient evaluations: 428
In [8]: res_ncg = sm.Probit(data.endog, data.exog).fit(method="ncg", avextol=1e-8)
Optimization terminated successfully.
Current function value: 12.818804
Iterations: 12
Function evaluations: 14
Gradient evaluations: 12
Hessian evaluations: 12
In [9]: res_powell = sm.Probit(data.endog, data.exog).fit(method="powell", ftol=1e-8)
Optimization terminated successfully.
Current function value: 12.818804
Iterations: 12
Function evaluations: 568
All of the options for the solvers are available and are documented in the fit method. As you can see, some of the default values need to be changed to ensure (accurate) convergence. The Results objects that are returned have two new attributes.
In [10]: res_powell.mle_retvals
Out[10]:
{'converged': True,
'direc': array([[ 7.06629660e-02, -3.07499922e-03, 5.38418734e-01,
-4.19910465e-01],
[ 0.00000000e+00, 1.00000000e+00, 0.00000000e+00,
0.00000000e+00],
[ 1.49194876e+00, -6.64992809e-02, -6.96792443e-03,
-3.22306873e+00],
[ -5.36227277e-02, 1.18544093e-01, -8.75205765e-02,
-2.42149981e+00]]),
'fcalls': 568,
'fopt': 12.818804069990534,
'iterations': 12,
'warnflag': 0}
In [11]: res_powell.mle_settings
Out[11]:
{'callback': None,
'disp': 1,
'fargs': (),
'ftol': 1e-08,
'full_output': 1,
'maxfun': None,
'maxiter': 35,
'optimizer': 'powell',
'retall': 0,
'start_direc': None,
'start_params': [0, 0, 0, 0],
'xtol': 0.0001}
The dict mle_retvals contains all of the values that are returned from the solver if the full_output keyword is True. The dict mle_settings contains all of the arguments passed to the solver, including the defaults so that these can be checked after the fit. Again, all settings and returned values are documented in the fit method and in the results class, respectively.
Lastly, I started a GenericLikelihoodModel class. This is currently unfinished, though the basic idea is laid out. Take again the Probit example above using Lee Spector's educational program data. And assume we didn't have the Probit model from statsmodels. We could use the new GenericLikelihoodModel class. There are two ways (probably more) to proceed. For those comfortable with object oriented programming and inheritance in Python, we could subclass the GenericLikelihoodModel, defining our log-likelihood method.
from scikits.statsmodels import GenericLikelihoodModel as LLM
from scipy import stats
import numpy as np
class MyModel(LLM):
def loglike(self, params):
"""
Probit log-likelihood
"""
q = 2*self.endog - 1
X = self.exog
return np.add.reduce(stats.norm.logcdf(q*np.dot(X,params)))
from scipy import stats
import numpy as np
class MyModel(LLM):
def loglike(self, params):
"""
Probit log-likelihood
"""
q = 2*self.endog - 1
X = self.exog
return np.add.reduce(stats.norm.logcdf(q*np.dot(X,params)))
Now this model could be fit, using any of the methods that only require an objective function, i.e., Nelder-Mead or Powell.
In [43]: mod = MyModel(data.endog, data.exog)
In [44]: res = mod.fit(method="nm", maxiter=500)
Optimization terminated successfully.
Current function value: 12.818804
Iterations: 439
Function evaluations: 735
In [45]: res_nm.params
Out[45]: array([ 1.62580058, 0.05172931, 1.42632242, -7.45229725])
In [46]: res.params
Out[46]: array([ 1.62580058, 0.05172931, 1.42632242, -7.45229725])
In [44]: res = mod.fit(method="nm", maxiter=500)
Optimization terminated successfully.
Current function value: 12.818804
Iterations: 439
Function evaluations: 735
In [45]: res_nm.params
Out[45]: array([ 1.62580058, 0.05172931, 1.42632242, -7.45229725])
In [46]: res.params
Out[46]: array([ 1.62580058, 0.05172931, 1.42632242, -7.45229725])
The main drawback right now is that all statistics that rely on the covariance of the parameters, etc. will use numeric gradients and Hessians, which can lessen that accuracy of those statistics. This can be overcome by providing score and hessian methods as loglike was provided above. Of course, for more complicated likelihood functions this can soon become cumbersome. We are working towards more accurate numerical differentiation and discussing options for automatic or symbolic differentiation.
The main advantage as opposed to just writing your likelihood and passing it to a solver is that you have all of the (growing number of) statistics and tests available to statsmodels right in the generic model.
I would also like to accommodate those who are less familiar with OOP and inheritance in Python. I haven't quite worked out the final design for how this would go yet. Right now, you could do the following, though I don't think it quite meets the less complicated goal.
In [4]: from scikits.statsmodels.model import GenericLikelihoodModel as LLM
In [5]: import scikits.statsmodels as sm
In [6]: from scipy import stats
In [7]: import numpy as np
In [8]:
In [9]: data = sm.datasets.spector.load()
In [10]: data.exog = sm.add_constant(data.exog)
In [11]:
In [12]: def probitloglike(params, endog, exog):
....: """
....: Log likelihood for the probit
....: """
....: q = 2*endog - 1
....: X = exog
....: return np.add.reduce(stats.norm.logcdf(q*np.dot(X,params)))
....:
In [13]: mod = LLM(data.endog, data.exog, loglike=probitloglike)
In [14]: res = mod.fit(method="nm", fargs=(data.endog,data.exog), maxiter=500)
Optimization terminated successfully.
Current function value: 12.818804
Iterations: 439
Function evaluations: 735
In [15]: res.params
Out[15]: array([ 1.62580058, 0.05172931, 1.42632242, -7.45229725])
In [5]: import scikits.statsmodels as sm
In [6]: from scipy import stats
In [7]: import numpy as np
In [8]:
In [9]: data = sm.datasets.spector.load()
In [10]: data.exog = sm.add_constant(data.exog)
In [11]:
In [12]: def probitloglike(params, endog, exog):
....: """
....: Log likelihood for the probit
....: """
....: q = 2*endog - 1
....: X = exog
....: return np.add.reduce(stats.norm.logcdf(q*np.dot(X,params)))
....:
In [13]: mod = LLM(data.endog, data.exog, loglike=probitloglike)
In [14]: res = mod.fit(method="nm", fargs=(data.endog,data.exog), maxiter=500)
Optimization terminated successfully.
Current function value: 12.818804
Iterations: 439
Function evaluations: 735
In [15]: res.params
Out[15]: array([ 1.62580058, 0.05172931, 1.42632242, -7.45229725])
There are still a few design issues and bugs that need to be worked out with the last example, but the basic idea is there. That's all for now.
Monday, May 31, 2010
Week 1 GSoC Update
Last week was the first of the Google Summer of Code. I spent most of the week in a Bayesian econometrics class led by John Geweke and studying for a comprehensive exam that I take this week, so progress on statsmodels was rather slow. That said, I have been able to take care of some low hanging fruit.
There are a few name changes:
statsmodels/family -> statsmodels/families
statsmodels/lib/io.py -> statsmodels/iolib/foreign.py
Also Vincent has done a good bit of work on improving our output using the SimpleTable class from econpy. I will post some examples over the coming weeks, but SimpleTable provides an easy way to make tables in ASCII text, HTML, or LaTeX. The SimpleTable class has been moved
statsmodels/sandbox/ouput.py -> statsmodels/iolib/table.py
Beyond the renames, I have removed the soft dependency on RPy for running our tests in favor of hard-coded results, refactored our tests, and added a few additional ones along the way.
We are also making an effort to keep our online documentation synced with the current trunk. The biggest change to our documentation is the addition of a developer's page for those who might like to get involved. As always, please report problems with the docs on either the scipy-user list or join in the discussions of statsmodels, pandas, larry, and other topics on statistics and Python at the pystatsmodels Google group.
There are a few name changes:
statsmodels/family -> statsmodels/families
statsmodels/lib/io.py -> statsmodels/iolib/foreign.py
Also Vincent has done a good bit of work on improving our output using the SimpleTable class from econpy. I will post some examples over the coming weeks, but SimpleTable provides an easy way to make tables in ASCII text, HTML, or LaTeX. The SimpleTable class has been moved
statsmodels/sandbox/ouput.py -> statsmodels/iolib/table.py
Beyond the renames, I have removed the soft dependency on RPy for running our tests in favor of hard-coded results, refactored our tests, and added a few additional ones along the way.
We are also making an effort to keep our online documentation synced with the current trunk. The biggest change to our documentation is the addition of a developer's page for those who might like to get involved. As always, please report problems with the docs on either the scipy-user list or join in the discussions of statsmodels, pandas, larry, and other topics on statistics and Python at the pystatsmodels Google group.
Saturday, May 1, 2010
Plans for the Summer
A quick update on the plans for statsmodels over the next few months.
I have been accepted for my second Google Summer of Code, which means that we will have a chance to make a big push to get a lot of our work out of the sandbox, tested, and included in the main code base.
You can see the roadmap on Google's GSoC site here. You might have to log in to view it.
The quick version follows. As far as general issues, I will be getting the code ready for Python 3 and focusing on some design issues including an improved generic maximum likelihood framework, post-estimation testing, variable name handling, and output in text tables, LaTeX, and html. I will then be working to get a lot of our code out of the sandbox. This includes timeseries convenience functions and models such as GARCH, VARMA, Hodrick-Prescott filter, and a state space model that uses the Kalman filter. I will be polishing the systems of equation framework and panel (longitudinal) data estimators. We have also been working on some nonparametric estimators including univariate kernel density estimators and kernel regression estimators. Finally, as part of my coursework I have been working toward (generalized) maximum entropy models that I hope to include as well as some work on the scipy.maxentropy module.
I will give a quick talk on the project for the SciPy Conference in Austin.
It looks like we are set to make a good deal of progress on the code this summer.
I have been accepted for my second Google Summer of Code, which means that we will have a chance to make a big push to get a lot of our work out of the sandbox, tested, and included in the main code base.
You can see the roadmap on Google's GSoC site here. You might have to log in to view it.
The quick version follows. As far as general issues, I will be getting the code ready for Python 3 and focusing on some design issues including an improved generic maximum likelihood framework, post-estimation testing, variable name handling, and output in text tables, LaTeX, and html. I will then be working to get a lot of our code out of the sandbox. This includes timeseries convenience functions and models such as GARCH, VARMA, Hodrick-Prescott filter, and a state space model that uses the Kalman filter. I will be polishing the systems of equation framework and panel (longitudinal) data estimators. We have also been working on some nonparametric estimators including univariate kernel density estimators and kernel regression estimators. Finally, as part of my coursework I have been working toward (generalized) maximum entropy models that I hope to include as well as some work on the scipy.maxentropy module.
I will give a quick talk on the project for the SciPy Conference in Austin.
It looks like we are set to make a good deal of progress on the code this summer.
Monday, March 8, 2010
Sparse Least Squares Solver
I have a homework doing some monte carlo experiments of an autoregressive process of order 1, and I thought I would use it as an example to demonstrate the sparse least squares solver that Stefan committed to scipy revision 6251.
All mistakes are mine...
Given an AR(1) process
 "y_{t}=.9y_{t-1} + .01\epsilon_{t} \newline \newline \text{where} \newline \newline \epsilon_{t} \sim \boldsymbol{\text{NID} }\left(0,1\right)")
We can estimate the following autoregressive coefficients.
I'm curious if there's any downside to using sparse least squares whenever the RHS of a least squares can be written in block diagonal form.
All mistakes are mine...
Given an AR(1) process
We can estimate the following autoregressive coefficients.
In [1]: import numpy as np
In [2]: np.set_printoptions(threshold=25)
In [3]: np.random.seed(1)
In [4]: # make 1000 autoregressive series of length 100
In [5]: # y_0 = 0 by assumption
In [6]: samples = np.zeros((100,1000))
In [7]: for i in range(1,100):
...: error = np.random.randn(1,1000)
...: samples[i] = .9 * samples[i-1] + .01 * error
...:
In [8]: from scipy import sparse
In [9]: from scipy.sparse import linalg as spla
In [10]: # make block diagonal sparse matrix of y_t-1
In [11]: # recommended to build as a linked list
In [12]: spX = sparse.lil_matrix((99*1000,1000))
In [13]: for i in range(1000):
....: spX[i*99:(i+1)*99,i] = samples[:-1,i][:,None]
....:
In [14]: spX = spX.tocsr() # convert it to csr for performance
In [15]: # do the least squares
In [16]: retval = spla.isolve.lsqr(spX, samples[1:,:].ravel('F'), calc_var=True)
In [17]: retval[0]
Out[17]:
array([ 0.88347438, 0.8474124 , 0.85282674, ..., 0.91019165,
0.89698465, 0.76895806])
In [2]: np.set_printoptions(threshold=25)
In [3]: np.random.seed(1)
In [4]: # make 1000 autoregressive series of length 100
In [5]: # y_0 = 0 by assumption
In [6]: samples = np.zeros((100,1000))
In [7]: for i in range(1,100):
...: error = np.random.randn(1,1000)
...: samples[i] = .9 * samples[i-1] + .01 * error
...:
In [8]: from scipy import sparse
In [9]: from scipy.sparse import linalg as spla
In [10]: # make block diagonal sparse matrix of y_t-1
In [11]: # recommended to build as a linked list
In [12]: spX = sparse.lil_matrix((99*1000,1000))
In [13]: for i in range(1000):
....: spX[i*99:(i+1)*99,i] = samples[:-1,i][:,None]
....:
In [14]: spX = spX.tocsr() # convert it to csr for performance
In [15]: # do the least squares
In [16]: retval = spla.isolve.lsqr(spX, samples[1:,:].ravel('F'), calc_var=True)
In [17]: retval[0]
Out[17]:
array([ 0.88347438, 0.8474124 , 0.85282674, ..., 0.91019165,
0.89698465, 0.76895806])
I'm curious if there's any downside to using sparse least squares whenever the RHS of a least squares can be written in block diagonal form.
Tuesday, February 16, 2010
scikits.statsmodels 0.2.0 release
While I find no time to blog, I thought I'd post our newest release announcement here.
We are happy to announce the 0.2.0 (beta) release of scikits.statsmodels. This is both a bug-fix and new feature release.
Download
------------
You can easy_install (or PyPI URL:
http://pypi.python.org/pypi/scikits.statsmodels/)
Source downloads: http://sourceforge.net/projects/statsmodels/
Development branches: http://code.launchpad.net/statsmodels
Note that the trunk branch on launchpad is almost always stable and has the most up to date changes since our releases are so few and far between.
Documentation
------------------
http://statsmodels.sourceforge.net/
We invite you to install, kick the tires, and make bug reports and feature requests.
Feedback can either be on scipy-user or the mailing list at
http://groups.google.com/group/pystatsmodels?hl=en
Bug tracker: https://bugs.launchpad.net/statsmodels
Main Changes in 0.2.0
---------------------------------
* Improved documentation and expanded and more examples
* Added four discrete choice models: Poisson, Probit, Logit, and Multinomial Logit.
* Added PyDTA. Tools for reading Stata binary datasets (*.dta) and putting them into numpy arrays.
* Added four new datasets for examples and tests.
* Results classes have been refactored to use lazy evaluation.
* Improved support for maximum likelihood estimation.
* bugfixes
* renames for more consistency
RLM.fitted_values -> RLM.fittedvalues
GLMResults.resid_dev -> GLMResults.resid_deviance
Sandbox
-------------
We are continuing to work on support for systems of equations models, panel data models, time series analysis, and information and entropy econometrics in the sandbox. This code is often merged into trunk as it becomes more robust.
We are happy to announce the 0.2.0 (beta) release of scikits.statsmodels. This is both a bug-fix and new feature release.
Download
------------
You can easy_install (or PyPI URL:
http://pypi.python.org/pypi/scikits.statsmodels/)
Source downloads: http://sourceforge.net/projects/statsmodels/
Development branches: http://code.launchpad.net/statsmodels
Note that the trunk branch on launchpad is almost always stable and has the most up to date changes since our releases are so few and far between.
Documentation
------------------
http://statsmodels.sourceforge.net/
We invite you to install, kick the tires, and make bug reports and feature requests.
Feedback can either be on scipy-user or the mailing list at
http://groups.google.com/group/pystatsmodels?hl=en
Bug tracker: https://bugs.launchpad.net/statsmodels
Main Changes in 0.2.0
---------------------------------
* Improved documentation and expanded and more examples
* Added four discrete choice models: Poisson, Probit, Logit, and Multinomial Logit.
* Added PyDTA. Tools for reading Stata binary datasets (*.dta) and putting them into numpy arrays.
* Added four new datasets for examples and tests.
* Results classes have been refactored to use lazy evaluation.
* Improved support for maximum likelihood estimation.
* bugfixes
* renames for more consistency
RLM.fitted_values -> RLM.fittedvalues
GLMResults.resid_dev -> GLMResults.resid_deviance
Sandbox
-------------
We are continuing to work on support for systems of equations models, panel data models, time series analysis, and information and entropy econometrics in the sandbox. This code is often merged into trunk as it becomes more robust.
Monday, August 31, 2009
scikits.statsmodels Release Announcement
We have been working hard to get a release ready for general consumption for the statsmodels code. Well, we're happy to announce that a (very) beta release is ready.
Background
==========
The statsmodels code was started by Jonathan Taylor and was formerly included as part of scipy. It was taken up to be tested, corrected, and extended as part of the Google Summer of Code 2009.
What it is
==========
We are now releasing the efforts of the last few months under the scikits namespace as scikits.statsmodels. Statsmodels is a pure python package that requires numpy and scipy. It offers a convenient interface for fitting parameterized statistical models with growing support for displaying univariate and multivariate summary statistics, regression summaries, and (postestimation) statistical tests.
Main Feautures
==============
* regression: Generalized least squares (including weighted least squares and least squares with autoregressive errors), ordinary least squares.
* glm: Generalized linear models with support for all of the one-parameter exponential family distributions.
* rlm: Robust linear models with support for several M-estimators.
* datasets: Datasets to be distributed and used for examples and in testing.
There is also a sandbox which contains code for generalized additive models (untested), mixed effects models, cox proportional hazards model (both are untested and still dependent on the nipy formula framework), generating descriptive statistics, and printing table output to ascii, latex, and html. None of this code is considered "production ready".
Where to get it
===============
Development branches will be on LaunchPad. This is where to go to get the most up to date code in the trunk branch. Experimental code will also be hosted here in different branches.
https://code.launchpad.net/statsmodels
Source download of stable tags will be on SourceForge.
https://sourceforge.net/projects/statsmodels/
or
PyPi: http://pypi.python.org/pypi/scikits.statsmodels/
License
=======
Simplified BSD
Documentation
=============
The official documentation is hosted on SourceForge.
http://statsmodels.sourceforge.net/
The sphinx docs are currently undergoing a lot of work. They are not yet comprehensive, but should get you started.
This blog will continue to be updated as we make progress on the code.
Discussion and Development
==========================
All chatter will take place on the or scipy-user mailing list. We are very interested in receiving feedback about usability, suggestions for improvements, and bug reports via the mailing list or the bug tracker at https://bugs.launchpad.net/statsmodels.
Background
==========
The statsmodels code was started by Jonathan Taylor and was formerly included as part of scipy. It was taken up to be tested, corrected, and extended as part of the Google Summer of Code 2009.
What it is
==========
We are now releasing the efforts of the last few months under the scikits namespace as scikits.statsmodels. Statsmodels is a pure python package that requires numpy and scipy. It offers a convenient interface for fitting parameterized statistical models with growing support for displaying univariate and multivariate summary statistics, regression summaries, and (postestimation) statistical tests.
Main Feautures
==============
* regression: Generalized least squares (including weighted least squares and least squares with autoregressive errors), ordinary least squares.
* glm: Generalized linear models with support for all of the one-parameter exponential family distributions.
* rlm: Robust linear models with support for several M-estimators.
* datasets: Datasets to be distributed and used for examples and in testing.
There is also a sandbox which contains code for generalized additive models (untested), mixed effects models, cox proportional hazards model (both are untested and still dependent on the nipy formula framework), generating descriptive statistics, and printing table output to ascii, latex, and html. None of this code is considered "production ready".
Where to get it
===============
Development branches will be on LaunchPad. This is where to go to get the most up to date code in the trunk branch. Experimental code will also be hosted here in different branches.
https://code.launchpad.net/statsmodels
Source download of stable tags will be on SourceForge.
https://sourceforge.net/projects/statsmodels/
or
PyPi: http://pypi.python.org/pypi/scikits.statsmodels/
License
=======
Simplified BSD
Documentation
=============
The official documentation is hosted on SourceForge.
http://statsmodels.sourceforge.net/
The sphinx docs are currently undergoing a lot of work. They are not yet comprehensive, but should get you started.
This blog will continue to be updated as we make progress on the code.
Discussion and Development
==========================
All chatter will take place on the or scipy-user mailing list. We are very interested in receiving feedback about usability, suggestions for improvements, and bug reports via the mailing list or the bug tracker at https://bugs.launchpad.net/statsmodels.
Thursday, August 27, 2009
GSoC Is Over
Whoa, where did the last month go? The Google Summer of Code 2009 officially ended this Monday. Though I haven't taken a breath to update the blog, we (Josef and I) have been hard at work on the models code.
We have working and tested versions of Generalized Least Squares, Weighted Least Squares, Ordinary Least Squares, Robust Linear Models with several M-estimators, and Generalized Linear Models with support for all (almost all?) one parameter exponential family distributions. We have also provided some more convenience functions, created a standalone python package for the models code, and obtained permissions to distribute a few more datasets. Due to a lack of time, there is only experimental (read untested) support for autoregressive models, mixed effects models, generalized additive models, and convenience functions for returning strings (possibly html and latex output as well) with regression results and descriptive statistics. I will continue to work on these as I find time.
I will soon post a note on the progress that was made in the robust linear models code. Also, look out for a (semi-) official release of the code in the next few days. We have decided to name the project statsmodels and distribute it as a scikit. We need to finalize the documentation (should be ready to go in the next day or so...I am back taking courses) and clean up some of the usage examples, so people can jump right in and use the code, give feedback, and hopefully contribute extensions and new models.
As for the future of statsmodels, we are discussing over the next few weeks the immediate extensions that we know would like to make. It's looking like I will be wearing my microeconometrician hat this semester in my own coursework. More specifically, I will probably be working with cross-sectional and panel data models for household survey data in my own research and finding some time for time series models as part of my teaching assistantship. Josef has also mentioned wanting to work more with time series models.
If anyone (especially those from other disciplines) would like to contribute or see some extensions (my apologies to those who have made requests that I haven't yet been able to accomodate) feel free to post to the scipy-dev mailing list. I'm more than happy to discuss/debate with users and potential developers the design decisions that have been made, as I think the code is still in an unsettled enough state to merit some discussion.
We have working and tested versions of Generalized Least Squares, Weighted Least Squares, Ordinary Least Squares, Robust Linear Models with several M-estimators, and Generalized Linear Models with support for all (almost all?) one parameter exponential family distributions. We have also provided some more convenience functions, created a standalone python package for the models code, and obtained permissions to distribute a few more datasets. Due to a lack of time, there is only experimental (read untested) support for autoregressive models, mixed effects models, generalized additive models, and convenience functions for returning strings (possibly html and latex output as well) with regression results and descriptive statistics. I will continue to work on these as I find time.
I will soon post a note on the progress that was made in the robust linear models code. Also, look out for a (semi-) official release of the code in the next few days. We have decided to name the project statsmodels and distribute it as a scikit. We need to finalize the documentation (should be ready to go in the next day or so...I am back taking courses) and clean up some of the usage examples, so people can jump right in and use the code, give feedback, and hopefully contribute extensions and new models.
As for the future of statsmodels, we are discussing over the next few weeks the immediate extensions that we know would like to make. It's looking like I will be wearing my microeconometrician hat this semester in my own coursework. More specifically, I will probably be working with cross-sectional and panel data models for household survey data in my own research and finding some time for time series models as part of my teaching assistantship. Josef has also mentioned wanting to work more with time series models.
If anyone (especially those from other disciplines) would like to contribute or see some extensions (my apologies to those who have made requests that I haven't yet been able to accomodate) feel free to post to the scipy-dev mailing list. I'm more than happy to discuss/debate with users and potential developers the design decisions that have been made, as I think the code is still in an unsettled enough state to merit some discussion.
Saturday, July 25, 2009
Iterated Reweighted Least Squares
I have spent the last two weeks putting the "finishing" touches on the generalized linear models and starting to go over the robust linear models (RLM). The test suite for GLM is not complete yet, but all of the exponential families are covered with at least their default link functions tested and are looking good. So in an effort to make a first pass over all of the existing code, I moved on to RLM. After the time spent with GLM theory, the RLMs theory and code was much more manageable.
Before discussing the RLMs, their implementation, and the extensions I have made. I will describe the iterated reweighted least squares (IRLS) algorithm for the GLMs to demonstrate the theory and the solution method in the models code. A very similar iteration is done for the RLMs as well.
The main idea of GLM, as noted, is to relate a response variable to a linear model via a link function, which allows us to use least squares regression. Let us take as an example, the binomial family (which is written to handle Bernoulli and binomial data). In this case, the response variable is Bernoulli, 1 indicates a "success" and 0 a "failure".
The default link for the binomial family is the logit link. So we have
=\ln\frac{\mu}{1-\mu} "\eta=g(u)=\ln\frac{\mu}{1-\mu}")
η is our linear predictor and μ is our actual mean response. The first thing that we need for the algorithm is to compute a first guess on μ (IRLS as opposed to Newton-Raphson makes a guess on the mean response rather than the parameter vector β). The algorithm is fairly robust to this first guess; however, a common choice is

For the binomial family, we specifically use

where y is our given response variable. We then use this first guess to initialize our linear predictor η via the link function given above. With these estimates we are able to start the iteration. Our convergence criteria is based on the deviance function, which is simply twice the log-likelihood ratio of our current guess on the fitted model versus the saturated log-likelihood.
 - \mathcal{L}\left(y;\mu \right )\right ] "D=2\phi\left[ \mathcal{L}\left(y;y \right ) - \mathcal{L}\left(y;\mu \right )\right ]")
Where Φ is a dispersion (scale) parameter. Note that the saturated log-likelihood is simply the likelihood of the perfectly fitted model where y = μ. For the binomial family the deviance function is
 & \text{, if }y_{i}=0\\ -2\ln\mu_{i} & \text{, if }y_{i}=1\end{cases} "\sum_{i}D_{i}=\begin{cases} -2\ln\left(1-\mu_{i}\right) & \text{, if }y_{i}=0\\ -2\ln\mu_{i} & \text{, if }y_{i}=1\end{cases}")
The iteration continues while the deviance function evaluated at the updated μ differs from the previous by the given convergence tolerance (default is 1e-08) and the number of iterations is less than the given maximum (default is 100).
The actual iterations, as the name of the algorithm suggests, run a weighted least squares fit of the actual regressors on the adjusted linear predictor (our transformed guess on the response variable). The adjustment is given by
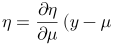 \\ \text{Recalling that }\eta=g(\mu) "\eta=\frac{\partial\eta}{\partial\mu}\left(y-\mu \right ) \\ \text{Recalling that }\eta=g(\mu)")
which moves us closer to the root of the estimating equation (see the previously mentioned Gill or Hardin and Hilbe for the details of root-finding using the Newton-Raphson method. IRLS is simply Newton-Raphson using some simplifications.). The only remaining ingredient is the choice of weights for the weighted least squares. Similar to other methods such as general least squares (GLS) that correct for heteroskedasticity in the error terms, a diagonal matrix containing estimates of the variance of the error terms is used. However, in our case, the exact form of this variance is unknown and difficult to estimate, but the error each estimate is assumed to vary with the mean response variable. Thus, we improve the weights at each step given our best guess for the mean response variable μ and the known variance function of each family. For the binomial family, as is well known, the variance function is
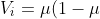 "V_{i}=\mu(1-\mu)")
Thus we can obtain an estimate of the parameters using weighted least squares. Using these estimates we update η
 "\eta=X\beta + \left(\text{offset}\right)")
Correcting by an offset if one is specified (the code currently does not support the use of offsets, but this would be a simple extension). Using this linear predictor (remember it was originally given by the linear transformation η = g(μ)) we update our guess on the mean response variable μ and use this to update our estimate of the deviance function. This is continued until convergence is reached.
Once the fit is obtained, the covariance matrix is obtained as always though in the case of GLM it is weighted by an estimate of the scale chosen when the fit method is called. The default is Pearson's Chi-Squared. The standard errors of the estimate are obtained from the diagonal elements of this matrix.
And that's basically it. Much of my time with the GLM code was spent getting my head around the theory and then this algorithm. Then I had to obtain data (Jeff Gill was kind enough to give permission for SciPy to use and distribute the datasets from his nice monograph) and write tests to ensure that all of the intermediate and final results were correct for each family. This was no small feat considering there are 6 families after I added the negative binomial family and around 25 possible combinations of families and link functions. Figuring out the correct use of the estimated scale (or dispersion) parameters for each family was particularly challenging. As I mentioned, in the interest of time, I haven't written tests for the noncanonical links for each and every family, but the initial results look good and these tests will come.
GLM provided a good base for understanding the remaining code and allowed me to more or less plow through the robust linear models estimator. I had some mathematical difficulties in extending the models to include the correct covariance matrices, since there is no strong theoretical consensus on what they should actually be! More on RLM in my next post, but before then I'll just give a quick look at how the GLM estimator is used.
First, the algorithm described above has been made flexible enough to estimate truly binomial data. That is, we can have a vector with each row containing (# of successes, # of failures) as is the case in the star98 data from Dr. Gill, described and included in the models.datasets. It will be useful to have a look at the syntax for this type of data as it's slightly different than the other families.
In [1]: import models
In [2]: import numpy as np
In [3]: from models.datasets.star98.data import load
In [4]: data = load()
In [5]: data.exog = models.functions.add_constant(data.exog)
In [6]: trials = data.endog[:,:2].sum(axis=1)
In [7]: data.endog[0] # (successes, failures)
Out[7]: array([ 452., 355.])
In [8]: trials[0] # total trials
Out[8]: 807.0
In [9]: from models.glm import GLMtwo as GLM # the name will change
In [10]: bin_model = GLM(data.endog, data.exog, family=models.family.Binomial())
In [11]: bin_results = bin_model.fit(data_weights = trials)
In [12]: bin_results.params
Out[12]:
array([ -1.68150366e-02, 9.92547661e-03, -1.87242148e-02,
-1.42385609e-02, 2.54487173e-01, 2.40693664e-01,
8.04086739e-02, -1.95216050e+00, -3.34086475e-01,
-1.69022168e-01, 4.91670212e-03, -3.57996435e-03,
-1.40765648e-02, -4.00499176e-03, -3.90639579e-03,
9.17143006e-02, 4.89898381e-02, 8.04073890e-03,
2.22009503e-04, -2.24924861e-03, 2.95887793e+00])
The main difference between the above and the rest of the families is that you must specify the total number of "trials" (which as you can see is just the sum of success and failures for each observation) as the data_weights argument to fit. This was done so that the current implementation of the Bernouilli family could be extended without rewriting its other derived functions. The code could easily (and might be) extended to calculate these trials so that this argument doesn't need to be specified, but it's sometimes better to be explicit.
Before discussing the RLMs, their implementation, and the extensions I have made. I will describe the iterated reweighted least squares (IRLS) algorithm for the GLMs to demonstrate the theory and the solution method in the models code. A very similar iteration is done for the RLMs as well.
The main idea of GLM, as noted, is to relate a response variable to a linear model via a link function, which allows us to use least squares regression. Let us take as an example, the binomial family (which is written to handle Bernoulli and binomial data). In this case, the response variable is Bernoulli, 1 indicates a "success" and 0 a "failure".
The default link for the binomial family is the logit link. So we have
η is our linear predictor and μ is our actual mean response. The first thing that we need for the algorithm is to compute a first guess on μ (IRLS as opposed to Newton-Raphson makes a guess on the mean response rather than the parameter vector β). The algorithm is fairly robust to this first guess; however, a common choice is
For the binomial family, we specifically use
where y is our given response variable. We then use this first guess to initialize our linear predictor η via the link function given above. With these estimates we are able to start the iteration. Our convergence criteria is based on the deviance function, which is simply twice the log-likelihood ratio of our current guess on the fitted model versus the saturated log-likelihood.
Where Φ is a dispersion (scale) parameter. Note that the saturated log-likelihood is simply the likelihood of the perfectly fitted model where y = μ. For the binomial family the deviance function is
The iteration continues while the deviance function evaluated at the updated μ differs from the previous by the given convergence tolerance (default is 1e-08) and the number of iterations is less than the given maximum (default is 100).
The actual iterations, as the name of the algorithm suggests, run a weighted least squares fit of the actual regressors on the adjusted linear predictor (our transformed guess on the response variable). The adjustment is given by
which moves us closer to the root of the estimating equation (see the previously mentioned Gill or Hardin and Hilbe for the details of root-finding using the Newton-Raphson method. IRLS is simply Newton-Raphson using some simplifications.). The only remaining ingredient is the choice of weights for the weighted least squares. Similar to other methods such as general least squares (GLS) that correct for heteroskedasticity in the error terms, a diagonal matrix containing estimates of the variance of the error terms is used. However, in our case, the exact form of this variance is unknown and difficult to estimate, but the error each estimate is assumed to vary with the mean response variable. Thus, we improve the weights at each step given our best guess for the mean response variable μ and the known variance function of each family. For the binomial family, as is well known, the variance function is
Thus we can obtain an estimate of the parameters using weighted least squares. Using these estimates we update η
Correcting by an offset if one is specified (the code currently does not support the use of offsets, but this would be a simple extension). Using this linear predictor (remember it was originally given by the linear transformation η = g(μ)) we update our guess on the mean response variable μ and use this to update our estimate of the deviance function. This is continued until convergence is reached.
Once the fit is obtained, the covariance matrix is obtained as always though in the case of GLM it is weighted by an estimate of the scale chosen when the fit method is called. The default is Pearson's Chi-Squared. The standard errors of the estimate are obtained from the diagonal elements of this matrix.
And that's basically it. Much of my time with the GLM code was spent getting my head around the theory and then this algorithm. Then I had to obtain data (Jeff Gill was kind enough to give permission for SciPy to use and distribute the datasets from his nice monograph) and write tests to ensure that all of the intermediate and final results were correct for each family. This was no small feat considering there are 6 families after I added the negative binomial family and around 25 possible combinations of families and link functions. Figuring out the correct use of the estimated scale (or dispersion) parameters for each family was particularly challenging. As I mentioned, in the interest of time, I haven't written tests for the noncanonical links for each and every family, but the initial results look good and these tests will come.
GLM provided a good base for understanding the remaining code and allowed me to more or less plow through the robust linear models estimator. I had some mathematical difficulties in extending the models to include the correct covariance matrices, since there is no strong theoretical consensus on what they should actually be! More on RLM in my next post, but before then I'll just give a quick look at how the GLM estimator is used.
First, the algorithm described above has been made flexible enough to estimate truly binomial data. That is, we can have a vector with each row containing (# of successes, # of failures) as is the case in the star98 data from Dr. Gill, described and included in the models.datasets. It will be useful to have a look at the syntax for this type of data as it's slightly different than the other families.
In [1]: import models
In [2]: import numpy as np
In [3]: from models.datasets.star98.data import load
In [4]: data = load()
In [5]: data.exog = models.functions.add_constant(data.exog)
In [6]: trials = data.endog[:,:2].sum(axis=1)
In [7]: data.endog[0] # (successes, failures)
Out[7]: array([ 452., 355.])
In [8]: trials[0] # total trials
Out[8]: 807.0
In [9]: from models.glm import GLMtwo as GLM # the name will change
In [10]: bin_model = GLM(data.endog, data.exog, family=models.family.Binomial())
In [11]: bin_results = bin_model.fit(data_weights = trials)
In [12]: bin_results.params
Out[12]:
array([ -1.68150366e-02, 9.92547661e-03, -1.87242148e-02,
-1.42385609e-02, 2.54487173e-01, 2.40693664e-01,
8.04086739e-02, -1.95216050e+00, -3.34086475e-01,
-1.69022168e-01, 4.91670212e-03, -3.57996435e-03,
-1.40765648e-02, -4.00499176e-03, -3.90639579e-03,
9.17143006e-02, 4.89898381e-02, 8.04073890e-03,
2.22009503e-04, -2.24924861e-03, 2.95887793e+00])
The main difference between the above and the rest of the families is that you must specify the total number of "trials" (which as you can see is just the sum of success and failures for each observation) as the data_weights argument to fit. This was done so that the current implementation of the Bernouilli family could be extended without rewriting its other derived functions. The code could easily (and might be) extended to calculate these trials so that this argument doesn't need to be specified, but it's sometimes better to be explicit.
Subscribe to:
Posts (Atom)
